😁 Hello, super humans! Everyone talks about chip progress as if it were a single number that gets smaller. Memory has never worked that way, and a Chinese fab just published enough detail to show why. Today we look at a DRAM node built out of patterning passes and capacitor geometry instead of shorter light, and at the price that trade quietly charges.
📰 Quick Signals
- 🧠 AI: Alibaba open-weighted Qwen-Image-2.1, a 7B unified image generator and editor with native transparency and up to ten reference images.
- 🤖 Robotics: Boston Dynamics opened a Robotics Metaplant Application Center inside Hyundai’s Metaplant America in Georgia, where Atlas now trains on real plant work.
- 💻 Programming: Kitty 0.49 added official custom shader support and claims 15 to 35% higher real-world throughput, which is a lot of headroom for a terminal.
- ⚡ Electronics: Revoy’s electric module slots between a diesel tractor and its trailer, turning an existing rig into a hybrid with up to 400 km of electric push and no truck replacement.
- 📡 Telecom: Most of the growth in telecom equipment revenue now traces back to AI build-out rather than to carrier network spending.
The Big Story: The shrink that came from masks, not from light
If you want to understand what an export control actually does to a process roadmap, DRAM is a better lens than logic. Logic hides its tricks behind marketing node names. Memory has to publish geometry, because geometry is the product.
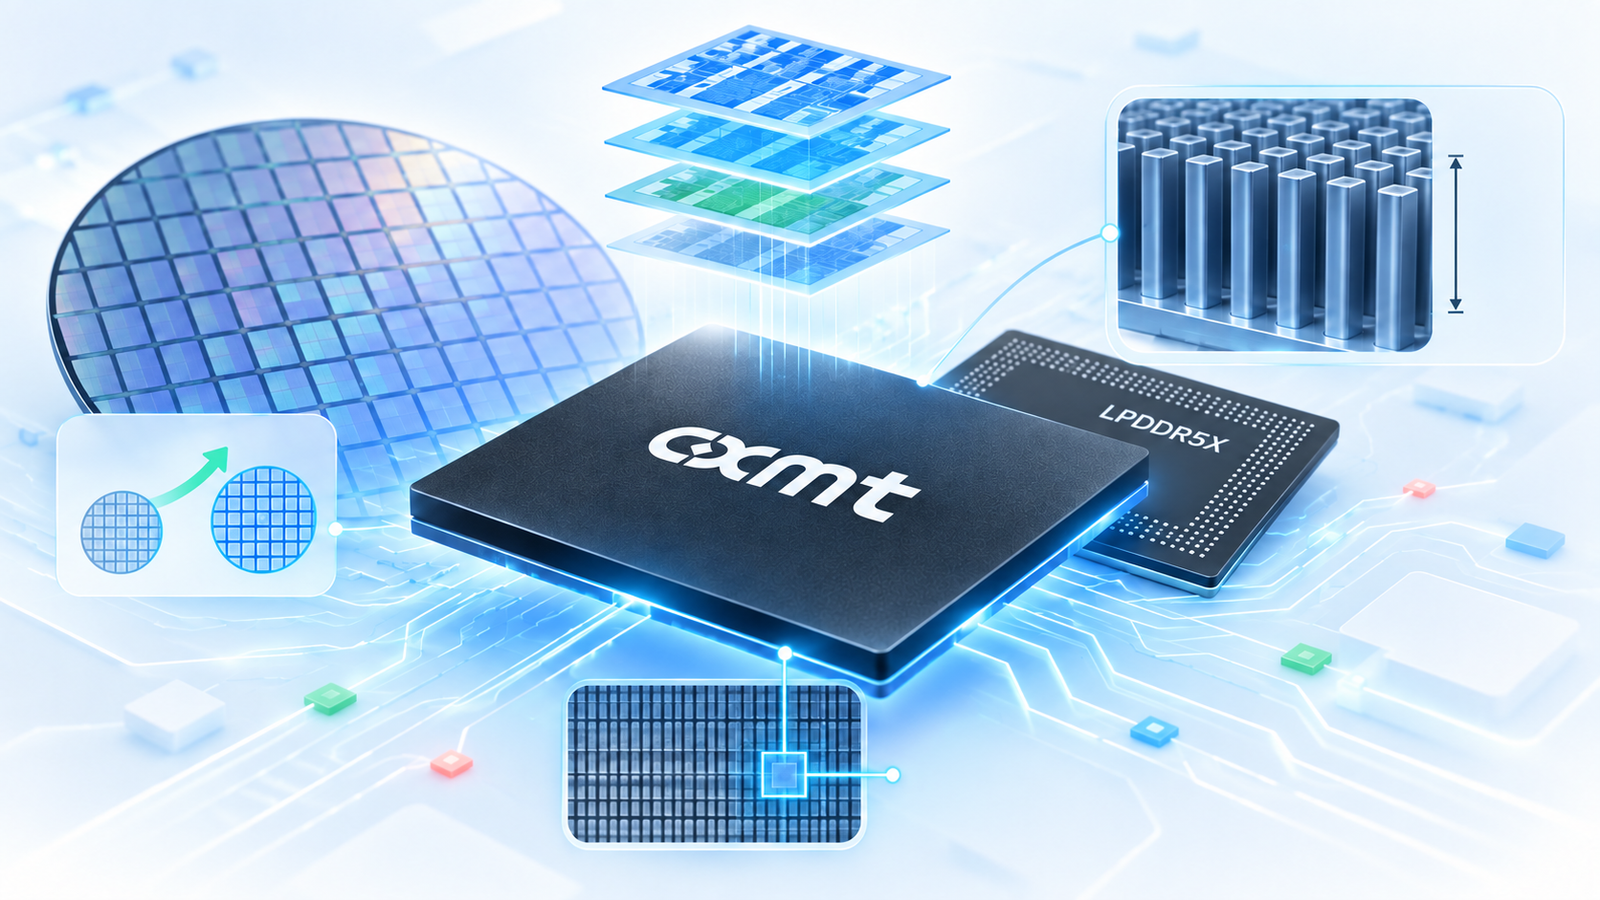
What happened: At the 2026 World Manufacturing Convention in Hefei on September 20, ChangXin Memory Technologies announced mass production of its fifth-generation DRAM platform, the G5, alongside a new LPDDR5X lineup. The reported specifications are unusually concrete: an 11.95 nm active-area half-pitch in the memory array, reached with quadruple patterning; a capacitor aspect ratio of 45:1; a core cell array height cut to 6,762 nm; and at least 50% more dies per wafer than the previous generation. Two 24 Gb LPDDR5X parts are already shipping, in 496-ball and 245-ball packages aimed at phones and portable consumer devices.
The details: Read those four numbers together and the whole strategy falls out. The active-area half-pitch is half the repeat distance of the array’s active region, and it is the honest way to describe DRAM density, which is why it is not comparable to a “12 nm class” label from Samsung, SK hynix or Micron: those names describe a process family, not a measured pitch. Getting to 11.95 nm without extreme ultraviolet means dividing the pitch in the mask shop instead of in the scanner. Quadruple patterning does that by repeating the key lithography and etch steps, halving the pitch twice, and each halving costs you deposition passes, etch passes, a tighter overlay budget and more places for a defect to land. You buy density with process steps, and you pay in cycle time and yield.
flowchart TB
    subgraph A["One exposure"]
        A1["mask pitch P"] --> A2["printed pitch P"]
    end
    subgraph B["Quadruple patterning"]
        B1["mask pitch P"] --> B2["pass 1: pitch P/2"]
        B2 --> B3["pass 2: pitch P/4"]
        B3 --> B4["11.95 nm AA half-pitch"]
    end
    B4 -.->|"you pay in"| C["extra deposition and etch steps"]
    B4 -.->|"you pay in"| D["tighter overlay budget"]
    B4 -.->|"you pay in"| E["more defect opportunities"]
    B4 -.->|"you gain"| F["at least 50% more dies per wafer"]
The other two numbers are the part people skip. A DRAM cell is one transistor and one capacitor, and the capacitor has to hold enough charge for the sense amplifier to read it. Shrink the footprint and the only way to keep that charge is to build upward, which is what a 45:1 aspect ratio means: a hole roughly forty-five times deeper than it is wide, etched, lined and filled without bowing, twisting or leaning into its neighbour. Meanwhile the core cell array height came down to 6,762 nm, so the array got denser in plan view while the capacitors got relatively taller. That combination, not the lithography alone, is what DRAM scaling has actually been for the last decade.
Important
Our take: The number I would hold onto is not 11.95 nm, it is “at least 50% more dies per wafer”, because that is the one a customer feels. It is also the one that is easiest to misread. Dies per wafer is a geometry claim: it tells you how many candidates the wafer holds, not how many pass test. Yield is the figure nobody in this industry publishes, and with quadruple patterning it is exactly the figure under pressure, since every extra masking pass multiplies the ways a die can die. So the honest reading is that CXMT has demonstrated the hard part, deep capacitors and a very tight array pitch on DUV, and has not told us what it costs per good die. That matters, because the whole point of a second source is price. If you build phones, the thing to watch over the next two quarters is not the node name but whether 24 Gb LPDDR5X supply from Hefei starts showing up in bills of materials at a price that moves the market.
🗞️ More News
🧠 AI
- Zhipu open-sourced ZCode after a data dispute and says it will add no-retention controls to its model-as-a-service offering.
- MiniMax open-sourced MiniMax Code, a terminal coding agent, which makes three Chinese labs shipping open agent tooling in a single week.
- Qwen3.8-Omni-Flash arrived with a one-million-token context window, pushing the long-context argument back toward the open-weight side.
- Huawei unveiled another run at Nvidia’s data center position, which is the compute half of the same import-substitution story as today’s Big Story.
- Nearly a quarter of UK adults now get at least some of their news through an AI assistant, which changes who the publisher’s actual reader is.
- Dynamic Semantic Compression moves inference out of token-by-token latent space to cut the memory overhead that dominates long-context serving.
- Google launched the Googlebook, and even sympathetic readers are struggling to name the job it does that something else does not.
🤖 Robotics
- Dongfeng’s Xiaodong humanoid is scheduled to start work in a factory in October, which puts a date on a claim that usually floats.
- Agility’s Digit 5 arrived with new legs, new batteries and safety upgrades, the least glamorous and most telling list a humanoid can ship.
- Unitree shares are down 53% from the IPO debut, a useful reality check next to the humanoid demo reels.
- Robotics investment hit $4.9B across 162 rounds in August, with the breakdown by technology and stage worth more than the headline number.
💻 Programming
- Rsync 3.5.1 cleans up path regressions from 3.5 and introduces protocol 33 plus 4 KiB logical block statistics.
- Peppermint OS started testing XLibre in place of the X.Org Server across its Debian and Devuan editions.
- Valve unveiled Lepton for running Android games on Linux, which is a bigger compatibility bet than the announcement makes it sound.
- MX Linux 25.3 “Infinity” shipped with Debian 13.7 updates, kernel 6.12, and Mesa 26.1 on the advanced hardware support editions.
⚡ Electronics
- Keysight brought 1.6T production test, 3.2T optical research gear and CEI-448G support to ECOC, which is where the interconnect claims get checked.
- Proposed FCC ISM band rules could break the LoRa mesh communities that grew up in the gaps of the current regime.
- The Sturgis, a converted Liberty ship carrying the MH-1A reactor, was the first floating nuclear power station, and its constraints read like a modern SMR spec sheet.
- The Mazda suitcase car is running again, which is still the best argument ever made for packaging constraints as a design brief.
📡 Telecom
- Lightera’s multicore fiber is carrying part of the OIF multi-vendor interoperability demo at ECOC, nudging space division multiplexing toward something deployable.
- The Ethernet Alliance is running a multi-vendor plugfest at ECOC spanning 400G, 800G and emerging 1.6T, the boring work that makes a standard real.
- Nokia is demonstrating an ultra-low-power 1.6T linear pluggable optics module and previewing 448 Gbps per lane at ECOC.
- Deutsche Telekom joined the travel eSIM market, which is now crowded enough that the margin story has to come from somewhere other than novelty.
- An Australian inquiry wants Telstra stripped of its role administering the Triple Zero emergency calling system in favour of a state-run body.
👨💻 Code Corner
“At least 50% more dies per wafer” sounds like a marketing line until you turn it into geometry. Here is the arithmetic, so you can tell how much shrink a claim like that actually implies.
"""How much smaller must a die get to fit 50% more of them on a 300 mm wafer?"""

import math


def gross_die_per_wafer(die_mm2: float, wafer_mm: float = 300.0) -> int:
    """Classic approximation: wafer area over die area, minus an edge-loss term."""
    radius = wafer_mm / 2
    area_term = math.pi * radius * radius / die_mm2
    edge_term = math.pi * wafer_mm / math.sqrt(2 * die_mm2)
    return int(area_term - edge_term)


def area_for_die_gain(die_mm2: float, gain: float = 1.5) -> float:
    """Largest die area that still yields `gain` times as many candidates."""
    target = gross_die_per_wafer(die_mm2) * gain
    low, high = 0.1, die_mm2
    for _ in range(80):
        mid = (low + high) / 2
        if gross_die_per_wafer(mid) < target:
            high = mid
        else:
            low = mid
    return low


if __name__ == "__main__":
    for die in (40.0, 55.0, 70.0):      # plausible mobile DRAM die sizes
        count = gross_die_per_wafer(die)
        shrunk = area_for_die_gain(die)
        print(f"{die:5.1f} mm2 -> {count:4d} gross die; "
              f"need {shrunk:5.2f} mm2 "
              f"({100 * (1 - shrunk / die):4.1f}% smaller) for +50%")
Tip
Run it and the answer is stable at roughly a third of the die area gone, across every starting size. That is the useful part: “50% more dies per wafer” is very nearly a restatement of “the die shrank by about a third”, independent of where you started. The edge term is why the two are not exactly equivalent, and it is also why small dies win twice: the partial dies around the wafer rim are a smaller fraction of the total. Note what the number still does not tell you, which is how many of those candidates survive test.
🧰 Toolbox
- Reality Check: a timed drill that shows you images and asks whether a model made them; good for calibrating how bad you have become at this.
- DavMail 7.0: the Exchange gateway that lets ordinary IMAP and CalDAV clients talk to Microsoft 365, now with faster sync.
- Rspamd 4.2: spam filtering with deeper Office and SVG attachment analysis, which is where a lot of current payloads hide.
- dSPACE software-in-the-loop: the digital twin environment the Indy Autonomous Challenge teams had to qualify in before touching a real car.
- OpenWrt and OPNsense on x86 e-waste: a walkthrough for turning a discarded thin client or mini PC into a router that outlives the one your ISP shipped.
🎬 Demo Watch (rotating)
Autonomous racecars overtook each other on a road course for the first time, at the Indy Autonomous Challenge event held at Laguna Seca ahead of the Grand Prix of Monterey. Unimore Racing, from the University of Modena and Reggio Emilia, won the final heat against Purdue AI Racing; nine university teams competed, and the run video includes passes through the Corkscrew.
Why it is hard: every prior IAC passing competition since 2022 ran on ovals. An oval gives you a wide, constant-radius geometry and a predictable racing line, so overtaking is mostly a speed-and-placement problem. A road course takes that away. Laguna Seca has elevation change, blind crests and corners where the grip budget is already spent on staying on the track, so a pass means predicting what another car’s policy will do at the limit, while you have nothing left in reserve. That is a multi-agent problem, not a trajectory-following one.
What is real and what is not: the hardware is deliberately identical across teams, same Dallara chassis, Honda engine, Luminar sensors and NVIDIA GPU, so the result is a clean comparison of driving policies rather than of budgets. The AI made every passing decision once a heat started. What it is not is autonomy in traffic: heats were one-on-one, teams qualified inside a dSPACE digital twin of the circuit before being allowed on track, human crews tuned parameters between laps, and a finger stayed on the e-stop throughout. The interesting result is not that a car passed another car, it is that the simulation-to-track transfer held up well enough to let them try.
📚 From the Blog
- Turning Pixels Into Something the AI Can Eat: episode three of the video analytics series, on decoding, preprocessing and the pixel formats a model will actually accept.
- Building Your First Neuron From Scratch: weights, bias, activation and the nudge that makes learning happen, worked through by hand.
- The Network Behind the Cameras: the plumbing that moves pixels without choking, and a good companion to today’s Big Story if you like watching a system hit a physical ceiling.
😀 The Bot Says…
A San Francisco shop is being “managed” by an AI model, and the write-up is a slow-motion comedy. Given the authority to choose its own inventory, the model filled the shelves with bric-a-brac that shares no visible theme; there is a human behind the counter, but purchases have to be negotiated with the model by voice. The store is burning through its startup money with no profit in sight, and one of the line items on the budget is the token cost of running the manager. The full account is worth your coffee break.
That’s all for today! Reply and tell us: would you buy a phone with memory from a second source, if it shaved real money off the price?