😁 Hello, super humans! Yesterday two labs shipped frontier-class models within about an hour and a half of each other, and both led with the price. Read past the per-token table, though, and the real announcement is hiding one row down, in the line almost nobody quotes: what it costs to re-read context you already sent. Today we follow the money into the cache.
📰 Quick Signals
- 🧠 AI: Xiaomi put its MiMo-V2.6 series on Hugging Face under MIT, including a 309B-parameter Flash MoE with 15B active parameters and a 256K context window.
- 🤖 Robotics: Alphabet’s Intrinsic open-sourced Intrinsic Core under Apache 2.0 at ROSCon, with real-time control, pose estimation, motion and grasp planning, simulation and ROS drivers in one box.
- 💻 Programming: systemd 262 can now be built as a static PID 1, and brings better container, TPM and VM support along with it.
- ⚡ Electronics: Marvell took its optical DSPs to 2 nm with 400G per lane at ECOC, alongside 1.6T coherent optics and a 102.4T co-packaged optics platform.
- 📡 Telecom: Vodafone and Ericsson demonstrated real-time call translation and noise cancelling running inside the network’s IMS core, so no special handset or app is needed.
The Big Story: Two frontier models, one afternoon, and the price moved into the cache
If you run coding agents, your bill is not driven by the price of a token. It is driven by how many times you pay for the same tokens again, and yesterday both big labs quietly admitted it.
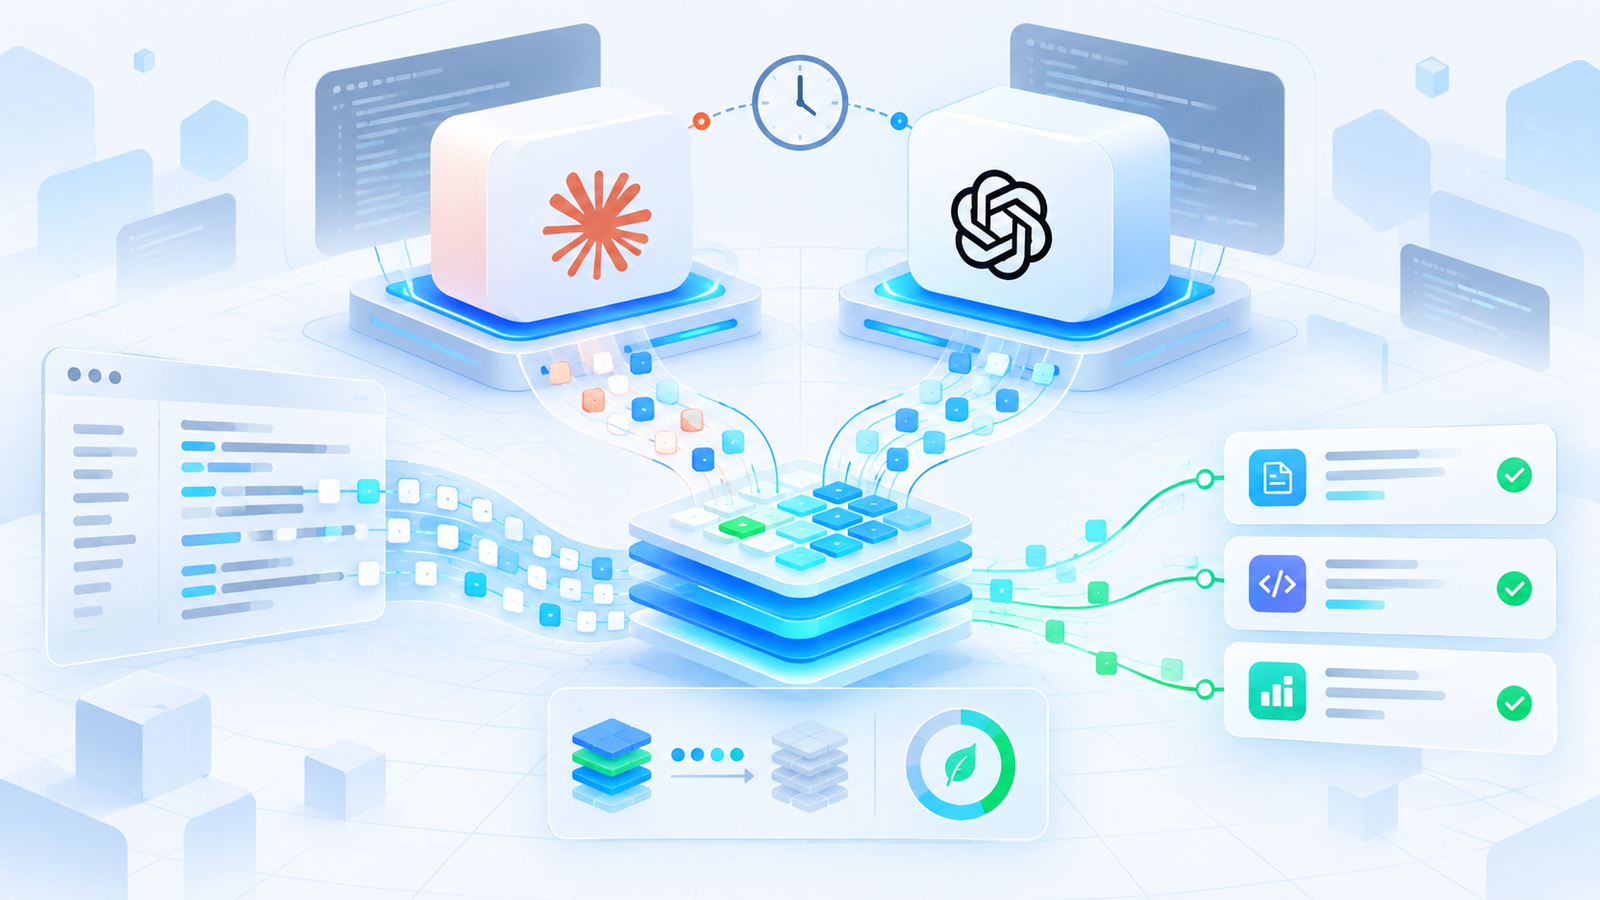
What happened: On September 22, Anthropic released Claude Opus 5.5 at $4 per million input tokens and $20 per million output, with cache reads at $0.20 per million, and said it costs 40% less than Opus 5 on typical workloads. Roughly 90 minutes later, OpenAI released GPT-6 Sol and GPT-6 Luna, cutting API prices by half versus the GPT-5.6 tier: Sol goes from $4/$20 to $2/$10 and Luna from $0.20/$1.20 to $0.10/$0.50. Both are live in their APIs today as claude-opus-5-5, gpt-6-sol and gpt-6-luna.
The details: Look at which prices actually moved. Opus 5.5’s input and output rates dropped 20% from Opus 5, but its cache-read rate dropped 60%, from $0.50 to $0.20, and Anthropic says outright that cache reads make up the majority of agentic and coding costs. OpenAI’s launch spends a whole section on caching: higher default hit rates, explicit breakpoints so you choose where a cached prefix ends, and the ability to change reasoning effort or toggle tools mid-conversation without invalidating the cache. It also quotes GitHub saying these changes cut the share of prompt tokens that need fresh processing by more than half. The reason is structural. An agent loop resends its entire context on every turn: the system prompt, the tool definitions, every file it has read and every step it has taken. Only the last few thousand tokens are new. Everything before them is a prefix the provider has already processed, and whether you pay full price or a tenth for it is the difference between an expensive agent and a cheap one.
flowchart LR
    subgraph T["Turn N of an agent loop"]
        A["System prompt + tools"] --> B["Files read so far"]
        B --> C["Steps 1..N-1"]
        C --> D["New step N"]
    end
    A -.->|"cache read, ~$0.20/M"| P["cached prefix"]
    B -.-> P
    C -.-> P
    D -->|"fresh input + cache write"| F["full-price tokens"]
    P --> R["what you actually pay per turn"]
    F --> R
The second tell is how both companies now report benchmarks. Anthropic plots Terminal-Bench 4.0 (66.4% for Opus 5.5) against cost per attempt and claims it matches GPT-6 Astra at about 40% of the cost; OpenAI plots AutomationBench and DeepSWE against cost per task and claims GPT-6 Sol beats Claude Opus 5 at 9% of its cost on the former. Neither chart is independent, and each lab picked the comparisons that flatter it. But the axis they agree on is the story: score per dollar of a finished task, which folds in token efficiency, caching and effort level, not score per token. One more line worth reading: OpenAI’s model page lists a long-context tier for Sol, where prompts above 272K input tokens are billed at a higher rate applied to the whole request, which matters a lot for agents that let their history grow unchecked.
Important
Our take: Stop comparing models by the price in the headline. If you build agents, the three numbers that decide your bill are cache-read price, cache hit rate, and tokens per finished task, and two of those three are properties of your harness rather than the model. Put your stable content (system prompt, tool schemas, repository map) at the front and never reorder it, append rather than rewrite history, and watch for long-context surcharges that kick in silently. Then rerun your own task suite on both new models with caching on, because the vendor charts measure their harnesses, not yours. My bet is that the gap between a well-cached and a badly-cached agent on the same model is now larger than the gap between these two labs.
🗞️ More News
🧠 AI
- Cisco Talos released CAIRN, a toolkit for hunting AI-integrated malware by its prompts and keys without running it, and disclosed an implant that orchestrates its own command and control across several models with no human operator.
- xAI’s Grok 4.7 landed at $2 input and $6 output per million tokens, making it the third frontier-class price cut in two days.
- The UN Security Council holds a session on AI and international security today, with OpenAI, Anthropic, DeepSeek and Moonshot representatives expected in the same room.
- Anthropic and OpenEvidence will offer a clinical decision support tool to physicians in about 100 low- and middle-income countries, free at the point of use.
- Six large banks, including Bank of America and Capital One, published principles for AI shopping agents and warned they could drive up scams, fraud and payment disputes.
- Snorkel AI raised $350 million at a $3.5 billion valuation on the back of selling finished datasets and RL environments to frontier labs.
- The Flash-dLLM paper finds GPU memory traffic is the bottleneck for diffusion language models and reports 5x to 11x speedups with a fused KV-cache kernel.
🤖 Robotics
- NVIDIA shipped Isaac ROS 5.0 with agent-ready skills for setup and manipulation, ROS 2 Lyrical support and FoundationPose tracking up to 5.5x faster.
- MIT’s insect-scale flying robot got a learned controller that makes it about 450% faster and lets it pull 10 somersaults in 11 seconds in a crosswind.
- Waymo launched Transit Rewards in the Bay Area, crediting a bus fare when a rider pairs a robotaxi trip with public transit on the same card.
- WiBotic, Burro and Nextpower laid out why outdoor robots fail in the field and what it takes to build ones that survive weather, dirt and charging.
💻 Programming
- NetBSD 10.2 is out with new hardware support and a batch of security fixes.
- KDE chose enterprise readiness, documentation and styling as its next community-wide goals.
- Flatpak 1.18.3 updates its Bubblewrap and xdg-dbus-proxy components and fixes regressions from 1.18.2.
- Google’s open-source agent orchestrator AX reached v0.3.0 and moved task state from Kubernetes custom resources to Redis Streams, because etcd was not built for millions of short-lived tasks.
- Valve is testing Pyrowave, a new low-latency codec for Steam Remote Play on Linux and SteamOS.
⚡ Electronics
- Taiwan’s ITRI disclosed a 3.2 Tbps silicon photonics optical engine aimed at AI and HPC interconnects.
- Teradyne announced the Iris 100, bringing semiconductor-grade test to microLED microdisplays and optical interconnects.
- Singapore startup Nexstrom wants to bring two-dimensional semiconductor materials into existing chip fabs.
- Raspberry Pi firmware now locks the RAM size to the board’s original specification, which ends DIY memory upgrades on newer boards.
📡 Telecom
- Klarna now bundles its unlimited UK mobile plan free with its top Max membership, riding Vodafone’s network through Gigs at a fraction of Vodafone’s own retail price.
- TalkTalk’s plan to break itself up is faltering, leaving the future of the UK broadband provider uncertain.
- Trade body Mobile UK backed calls for regulatory reform, claiming an overhaul would unlock 230 billion in economic gains.
👨💻 Code Corner
Here is today’s Big Story as arithmetic: a 40-turn agent task where every turn resends the growing context, priced with and without cache hits.
"""What does one agent task cost once prompt caching is in the picture?"""

PRICES = {  # USD per million tokens, from the Sept 22 launch posts
    "claude-opus-5-5": {"in": 4.00, "out": 20.00, "cache_read": 0.20, "cache_write": 5.00},
    "gpt-6-sol":       {"in": 2.00, "out": 10.00, "cache_read": 0.20, "cache_write": 2.50},
    "gpt-6-luna":      {"in": 0.10, "out": 0.50,  "cache_read": 0.01, "cache_write": 0.10},
}
LONG_CONTEXT = {"gpt-6-sol": (272_000, 2.0, 1.5)}  # threshold, input x, output x


def task_cost(model: str, turns: int = 40, system: int = 20_000,
              growth: int = 6_000, out_per_turn: int = 1_500,
              hit_rate: float = 0.9) -> float:
    """Each turn resends the whole context; the old prefix can be a cache hit."""
    p = PRICES[model]
    total, context = 0.0, system
    for _ in range(turns):
        in_x = out_x = 1.0
        limit = LONG_CONTEXT.get(model)
        if limit and context + growth > limit[0]:
            in_x, out_x = limit[1], limit[2]  # surcharge applies to the whole request
        prefix, fresh = context, growth
        total += prefix * (hit_rate * p["cache_read"] + (1 - hit_rate) * p["in"]) * in_x
        total += fresh * p["cache_write"] * in_x
        total += out_per_turn * p["out"] * out_x
        context += growth + out_per_turn
    return total / 1_000_000


if __name__ == "__main__":
    for model in PRICES:
        cold = task_cost(model, hit_rate=0.0)
        warm = task_cost(model, hit_rate=0.9)
        print(f"{model:16s} no cache ${cold:6.2f} | 90% hits ${warm:6.2f} "
              f"| saved {100 * (1 - warm / cold):4.1f}%")
With these assumptions the same task drops from about $29 to about $6 on Opus 5.5 and from about $19 to under $5 on Sol once 90% of the prefix hits the cache: caching moves the bill by more than switching vendors does.
Tip
Play with hit_rate first, then growth. A harness that rewrites its history (summarizing, reordering tool output, injecting a timestamp at the top) can drop the hit rate to near zero without you noticing; cost already grows with the square of the number of turns, and a cold cache multiplies that curve by roughly ten. The Luna cache rates and the Sol cache-write rate here are our reading of the published pricing, so check the providers’ pages before you budget with them.
🧰 Toolbox
- OpenAI prompt caching diagnostics: explains which parts of your requests missed the cache and why, which is exactly the number the Code Corner says to watch.
- Intrinsic Core on GitHub: the open-sourced control, planning and pose estimation stack, plus the Open Machine Tending reference design for FANUC and Universal Robots arms.
- KryonOS: a JavaScript operating system for ESP32 boards with screens, complete with a GUI, SD card access and an app store.
- LeafBus: swaps a dead Nanoleaf controller for an ESP32 that speaks the panels’ single-wire data bus and joins your network.
- NotepadNext 0.15: the cross-platform Notepad++ reimplementation gains split editor shortcuts, bulk tab closing and UTF-16 support.
- Raindrop radar notebook: a Python notebook that works through why raindrops behave like tiny dipole antennas in the Rayleigh regime, handy for anyone doing radar or rain-fade math.
🔌 Component of the Week (rotating)
TI MSPM0G5187, a Cortex-M0+ microcontroller at 80 MHz with 128 KB of flash and 32 KB of RAM, picked today because it is the other end of the inference-cost story: it carries TI’s TinyEngine NPU on die. TI claims up to 90x lower latency and more than 120x lower energy per inference than comparable MCUs without an accelerator, which is what makes always-on keyword spotting, vibration anomaly detection or simple gesture classification realistic on a coin-cell budget. The rest of the chip is a normal mixed-signal part, with USB 2.0, AES, a comparator and a DAC, so the model can sit right next to the sensor it listens to. It is priced under $1 in 1,000-unit quantities, and the LP-MSPM0G5187 LaunchPad costs $22 if you want to try it this week.
📚 From the Blog
- Turning Pixels Into Something the AI Can Eat: episode three of the video analytics series, on decoding, preprocessing and the pixel formats a model will actually accept.
- Building Your First Neuron From Scratch: weights, bias and activation worked through by hand, a good companion to today’s Big Story if you want to see what those millions of tokens are actually feeding.
- The Network Behind the Cameras: the plumbing that moves pixels across a network without choking it.
😀 The Bot Says…
OpenAI has reportedly fired contractors who were paid to rate ChatGPT’s answers, after catching them using AI to do the rating. According to 404 Media, one of the signals reviewers used to spot the culprits was an excessive number of em dashes. We have a strict no-em-dash rule in this newsletter, and for once we feel vindicated rather than fussy.
That’s all for today! Reply and tell us: do you know your agent’s cache hit rate, or did you just find out you should?