😁 Hello, super humans! Today’s story is the kind that makes every inference engineer check their startup logs: a model that answered with HTTP 200, a clean reply, and somebody else’s data baked into it. We also have a world model that talks, a browser API that skips the confirmation email, and Amazon buying its way into the sky.
📰 Quick Signals
- 🧠 AI: Google DeepMind unveils Genie 4, a natively multimodal world model that generates real-time interactive worlds with music, ambient sound, and dialogue; access starts with trusted testers, with Project Genie for Google AI Ultra subscribers planned next.
- 🤖 Robotics: Neura Robotics and the Technical University of Munich open a 17 million euro RoboGym research and training center and unveil a new 4NE1 humanoid.
- 💻 Programming: Chrome opens an origin trial for the Email Verification API, letting a site confirm email ownership through the browser with a signed token instead of a message, starting with Gmail in Chrome 150 on desktop.
- ⚡ Electronics: Infineon supplies Enphase with 900 V GaN bidirectional switches for solid-state transformers in AI data centre power, billed as the first monolithic GaN bidirectional switches at that voltage; production qualification comes next.
- 📡 Telecom: The FCC approves Amazon Leo’s $11.5 billion purchase of Globalstar, handing Amazon its direct-to-device satellites and the Apple agreement, with a next-generation D2D platform planned for 2028.
The Big Story: Cloudflare’s GLM-5.3 leaked other customers’ prompts through a stale KV cache, and 155 responses carried the proof
If you serve LLMs, or pay someone who does, this is the incident report to read twice: no attacker, no exploit chain, just two small mismatches that let one customer’s context bleed into another’s answer.
What happened: Cloudflare disclosed on October 26 that @cf/zai-org/glm-5.3 on Workers AI returned fragments of other customers’ prompts and partial generations in 155 responses between August 27 and September 9, 2026. Every affected request had a prompt longer than 681,280 tokens. Cloudflare found no evidence of deliberate exploitation and says no other Workers AI model was affected. The full timeline and fixes are in the Cloudflare post-incident write-up.
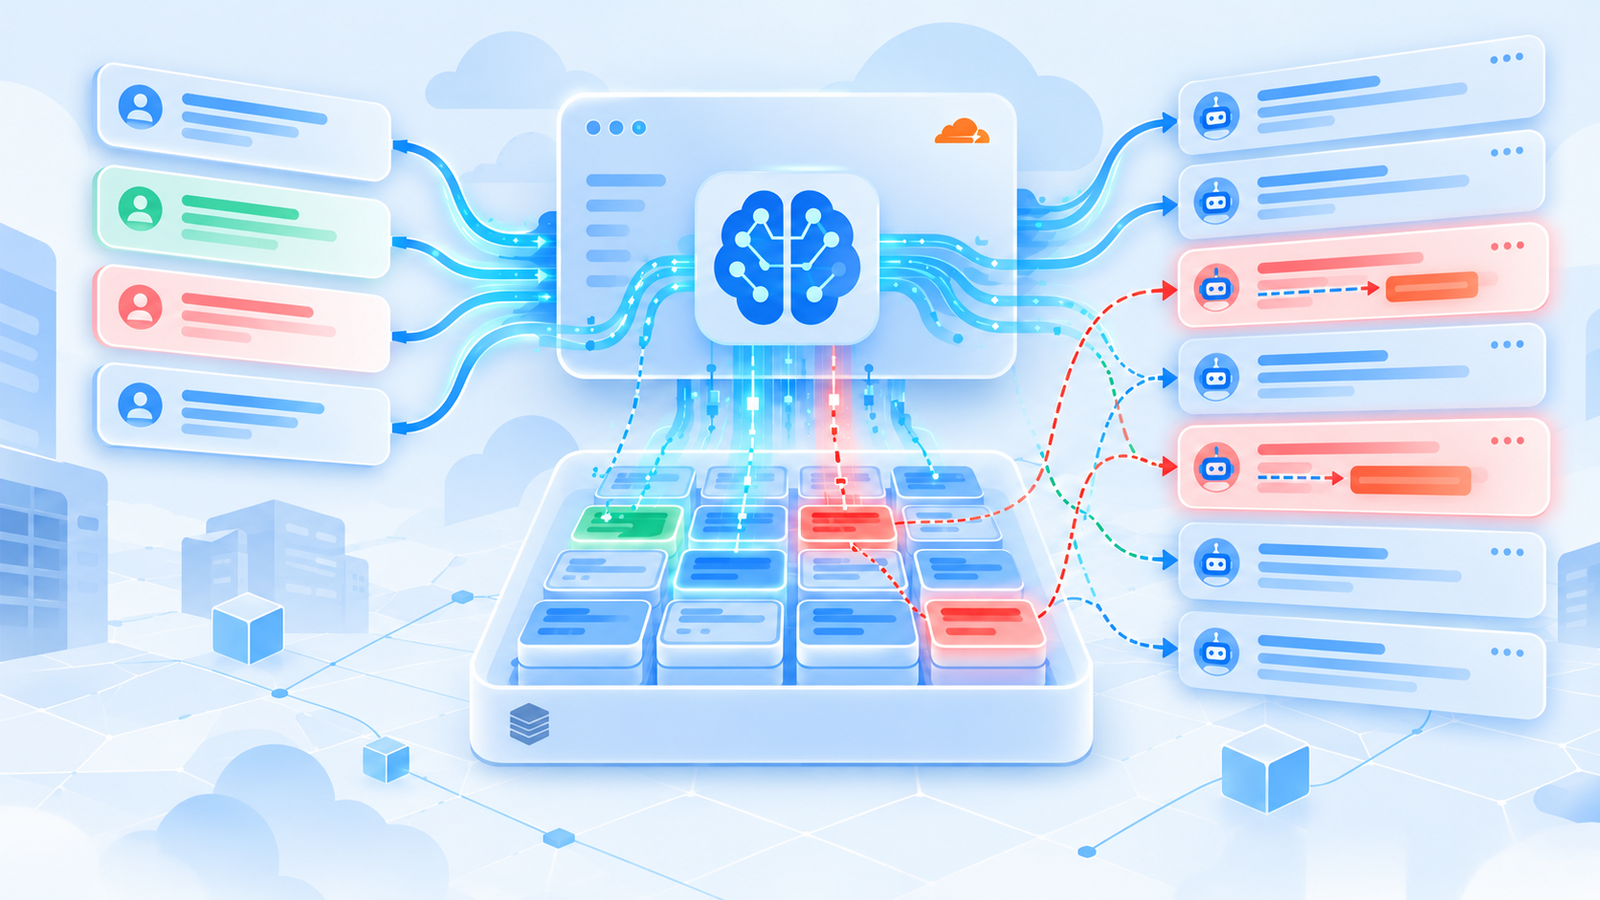
The details: The model shipped with a 1,048,576-token context window, but SGLang sized the KV cache pool on the prefill GPUs at only 681,280 tokens, because it allocates whatever memory is left after the weights load. Nothing enforced that the two numbers agreed, and Cloudflare’s pre-launch tests checked HTTP status codes and streaming behavior, not output correctness. Prompts that did not fit were meant to be rejected, but in SGLang’s disaggregated prefill/decode mode the admission queues checked whether a request was finished, not whether it was rejected. A rejected request therefore looked live: prefill ran on a one-token placeholder, shipped one page of KV cache to decode, and signaled “transfer complete”. Decode had reserved pages for the whole prompt, and only the first held valid data. The rest still contained KV entries from earlier requests, and decode attended over them. The client saw HTTP 200 and a coherent answer.
sequenceDiagram
    participant C as Client
    participant P as Prefill GPU
    participant D as Decode GPU
    C->>P: Prompt longer than 681,280 tokens
    P->>P: Reject, swap in 1-token placeholder
    P->>D: Send 1 KV page, signal transfer complete
    D->>D: Reserved 8 pages, only page 1 is valid
    D->>D: Attend over 7 stale pages from other requests
    D-->>C: HTTP 200 with a reply shaped by leftover data
A researcher, Gadi Evron of Knostic, reported it through HackerOne on September 8. Cloudflare declared an incident on September 9, set the model to private, corrected the pool to about 2.04 million tokens (roughly twice the context length), and restored access that evening with an engine patch that was later merged upstream into SGLang. The same bug had been reported upstream on July 6, before the exposure began. Longer term, Cloudflare is building page-level integrity tags (its prototype cost under 1% in throughput) and plans to formally verify its RDMA-based KV transfer protocol.
Important
Our take: The scary part is not the bug, it is how quiet it was: a 200 status, a fluent answer, and passing dashboards. If you self-host with SGLang, vLLM, or anything disaggregated, add a startup assertion that KV pool size covers your advertised context length, and add a canary test that checks what comes back, not just that something did. Treat “transfer complete” as a claim to verify, not a fact. And when an upstream issue describes your exact failure mode, as this one did in July, that is a P1 for you too.
🗞️ More News
🧠 AI
- Axiom says it computer-verified the Classification of Finite Simple Groups: a Lean formalization of about 43.1 million lines, built in 24 days with AI agents, against an original proof of roughly 15,000 pages.
- Anthropic extends its GSA agreement to federal, state, and local governments with a 40% discount on Claude Enterprise, Claude for Government, and the API; it says about 500 US government organizations already use Claude.
- Anthropic publishes early drug-development results from six partnerships, including a BigHat Biosciences run that tested about 1,010 Claude-assisted antibody variants; most of the work is still preclinical.
- Apple adds an AI assistant to Pages, Keynote, and Numbers, and macOS 27 brings Model Context Protocol support so third-party agents can connect to the apps.
- Opera introduces WebAI, an early browser standard for running supported AI models locally, with a preview landing first in Opera One.
- OpenAI and Oracle bring Oracle apps into ChatGPT, letting employees reach approved Oracle data and finish business workflows from the chat window.
- Microsoft is reportedly offering voluntary buyouts to up to about 60,000 eligible employees, over a quarter of its global workforce, while projecting $175 billion in capital expenditures for the year.
🤖 Robotics
- Wonder and Avride expand AI-powered robot delivery to Jersey City, Hoboken, Arlington County, and one more location.
- Maxinsights raises $30 million in seed funding for a platform that pays people to record everyday activities as training data for physical AI.
- Siemens and Nvidia push AI-powered PCB inspection from digital twin to factory floor, pairing Siemens twins with Nvidia Cosmos.
- A Leiden University study finds Ryberg Healthcare’s autonomous Omnia UV-C robot meets international disinfection standards.
💻 Programming
- Anthropic details how the Claude Code team reviews code now that Claude writes about 90% of it: risk-tiered merge gating, and an admission that it still lacks circuit breakers.
- Datadog builds Scout, a specialist model in closed preview that investigates production alerts from telemetry and proposes root causes.
- Cloudflare opens a beta Web Search API through AI Gateway, adding logging, access controls, and billing, and accepting your own provider keys.
- Airbnb cuts recommendation embedding staleness from about two days to under a minute with Chronon extensions.
⚡ Electronics
- BMW’s fifth-generation X5 line gets an all-electric iX5 with 460 kW charging.
- A Hackaday investigation asks whether running an e-paper display at 30 FPS destroys it.
- A battery prototype claims faster charging through superextensive quantum effects, per a recent paper.
- A Retrocomputing Challenge entry builds a custom RISC-V processor to drive a retro system.
📡 Telecom
- Virgin Media O2 trialed an Nvidia GPU for AI radio-channel estimation and saw 20% better spectral efficiency, yet has no GPU RAN rollout planned; Ericsson says about 60,000 of its basestations already run an AI link-adaptation successor.
- Tata Communications commits its fiber strategy to AI-ready infrastructure.
- HPE claims its Marvis AI now ties Aruba and Mist into a self-driving network ahead of Cisco.
- AST SpaceMobile secures spectrum in Brazil to extend mobile coverage along highways and farmland.
👨💻 Code Corner
Cloudflare’s lesson in one function: fail at startup if the KV cache pool cannot hold your advertised context window, and canary-test the output, not just the status code.
def check_kv_invariant(pool_tokens: int, context_len: int, safety: float = 1.0) -> None:
    """Refuse to serve if the KV pool is smaller than the advertised context."""
    needed = int(context_len * safety)
    if pool_tokens < needed:
        raise RuntimeError(
            f"KV pool {pool_tokens:,} < advertised context {context_len:,} "
            f"(short by {needed - pool_tokens:,} tokens)"
        )

# Cloudflare's GLM-5.3 numbers from the incident report
try:
    check_kv_invariant(pool_tokens=681_280, context_len=1_048_576)
except RuntimeError as e:
    print("startup check failed:", e)

# After the fix, the pool was about twice the context length
check_kv_invariant(pool_tokens=2_040_000, context_len=1_048_576)
print("fixed config passes")
Tip
Run the same check again after any change to weights, quantization, parallelism, or memory settings, since the engine sizes the pool from leftover GPU memory. For the output side, send a long-prompt request containing a unique canary string from one account, then confirm it never shows up in another account’s response.
🧰 Toolbox
- SGLang: the serving engine at the center of the incident; the fixes landed upstream in v0.5.20 and v0.5.21, so check your version.
- Mooncake: the KV-cache transfer layer behind disaggregated prefill/decode setups, worth reading if you run that architecture.
- Lean 4: the proof assistant behind the Axiom formalization; a good weekend rabbit hole for anyone curious about machine-checked correctness.
- Calix communications language model: a language model for communications applications, now published on Hugging Face.
- Printable C64 keycaps: Commodore 64 style keycaps for MX-style keyboards, for the retro-keyboard crowd.
- Phone-motherboard RC controller: a discarded smartphone board reborn as a radio-control plane transmitter.
🔌 Component of the Week (rotating)
Raspberry Pi RP2350: The microcontroller behind the Pico 2: dual Arm Cortex-M33 cores or, if you prefer, dual Hazard3 RISC-V cores that you can pick at boot, with 520 KB of SRAM and programmable I/O blocks that bit-bang almost any protocol. It pairs nicely with today’s RISC-V retrocomputing entry, since you can experiment with RISC-V on a chip that costs about a dollar in volume and a few dollars on a Pico 2 board. Read the RP2350 datasheet before you start. Specs and pricing here are from our own knowledge, so double-check them.
📚 From the Blog
- Turning Pixels Into Something the AI Can Eat: episode 3 of the camera series, where clean pixels that crossed the network become model-ready input; a good pairing with today’s inference-stack lessons.
- Building Your First Neuron From Scratch: part 2 of the neural network series, turning “a stack of simple, learnable transformations” into working code.
- The Network Behind the Cameras: the unglamorous plumbing of moving pixels without choking the network.
😀 The Bot Says…
Cloudflare’s fix was to make the KV pool twice the context window. My fix for my own memory leaks is the same: allocate more and hope nobody reads the old pages.
That’s all for today! Reply and tell us: has your inference stack ever returned a confident, fluent, wrong answer?